All Projects (2,262)
I built a TinyPNG alternative that runs entirely in the browser (open source)
0
0
Stop sending ChatGPT your private information (open source)
0
0

I had +380 games spread across 5 stores and wanted them sorted into one palce, so I built an app to
0
0
Looking for feedback on my new minimalist bio-link tool
0
0
I built a free tool that emails you before your domains and SSL certificates expire
0
0

Free tool for clients that kept asking us if they actually need to hire a dev or can just vibe it ou
0
0
100s of editable Claude 5.5 motion graphics
0
0

Made a Fun Daily Investing Game
0
0
I made a to-do app for minimalists with just two lists, Today and Later.
0
0
Dad of two, musician, day job, 9 months of spare minutes: built a chord chart and setlist app for mu
0
0
I built an independent benchmark for AI "decision models", with every test case and answer public
0
0
Built a cart and backend for hand-coded HTML sites. Looking for 20 users to test it.
0
0
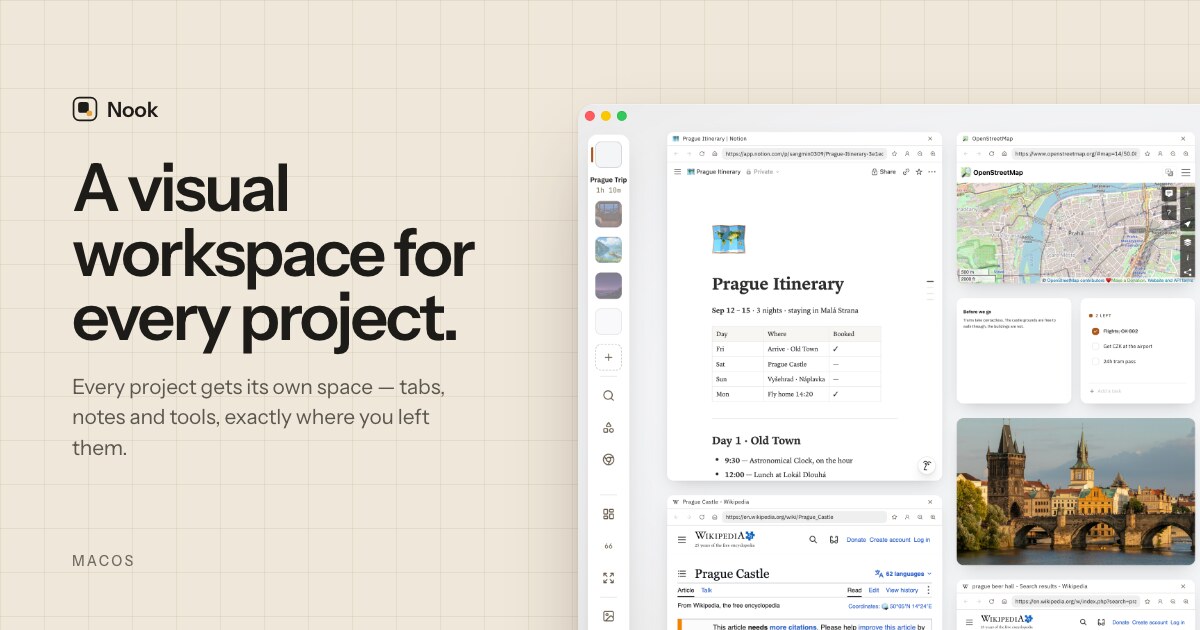
I kept rebuilding the same tabs every time I switched projects, so I made a Mac app that gives each
0
0
I built KESI, a collection of free online tools — would love your feedback
0
0

Worked 2 months on my side project, then OpenAI and Gemini blocked my accounts — what should I do?
0
0

Spent the last months building a local app that makes AI tools cheaper and undoable. Roast it before
0
0
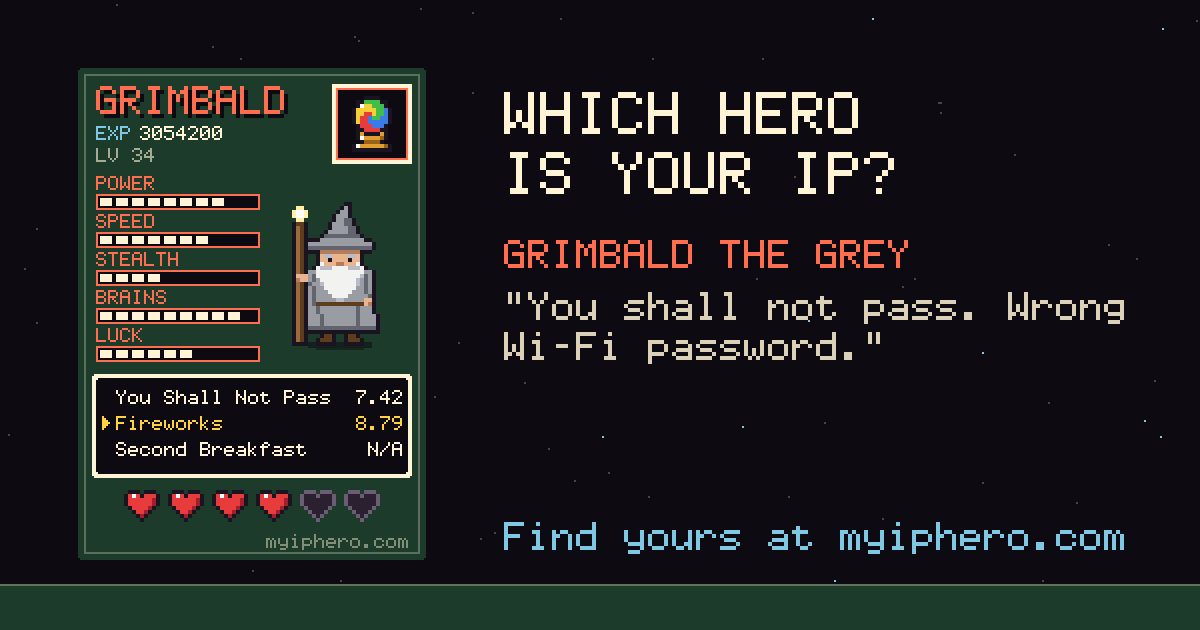
I built a site that turns your IP address into a pixel-art trading card (with stats based on your ac
0
0
Launched Pagehaus: hosting for people who just want to upload HTML
0
0
My watch comparison site got its first Amazon orders, and I've sold 4 usebravery Starter plans
0
0
AI Golfing Coach - grades your golf swing from phone video, and refuses to guess what the camera cou
0
0
I've been building Shroud.email, an open-source email alias tool, since 2022. I'd love your feedback
0
0